AI · SEMICONDUCTOR · FACT CHECK
 SKD WIRE
Mostly True
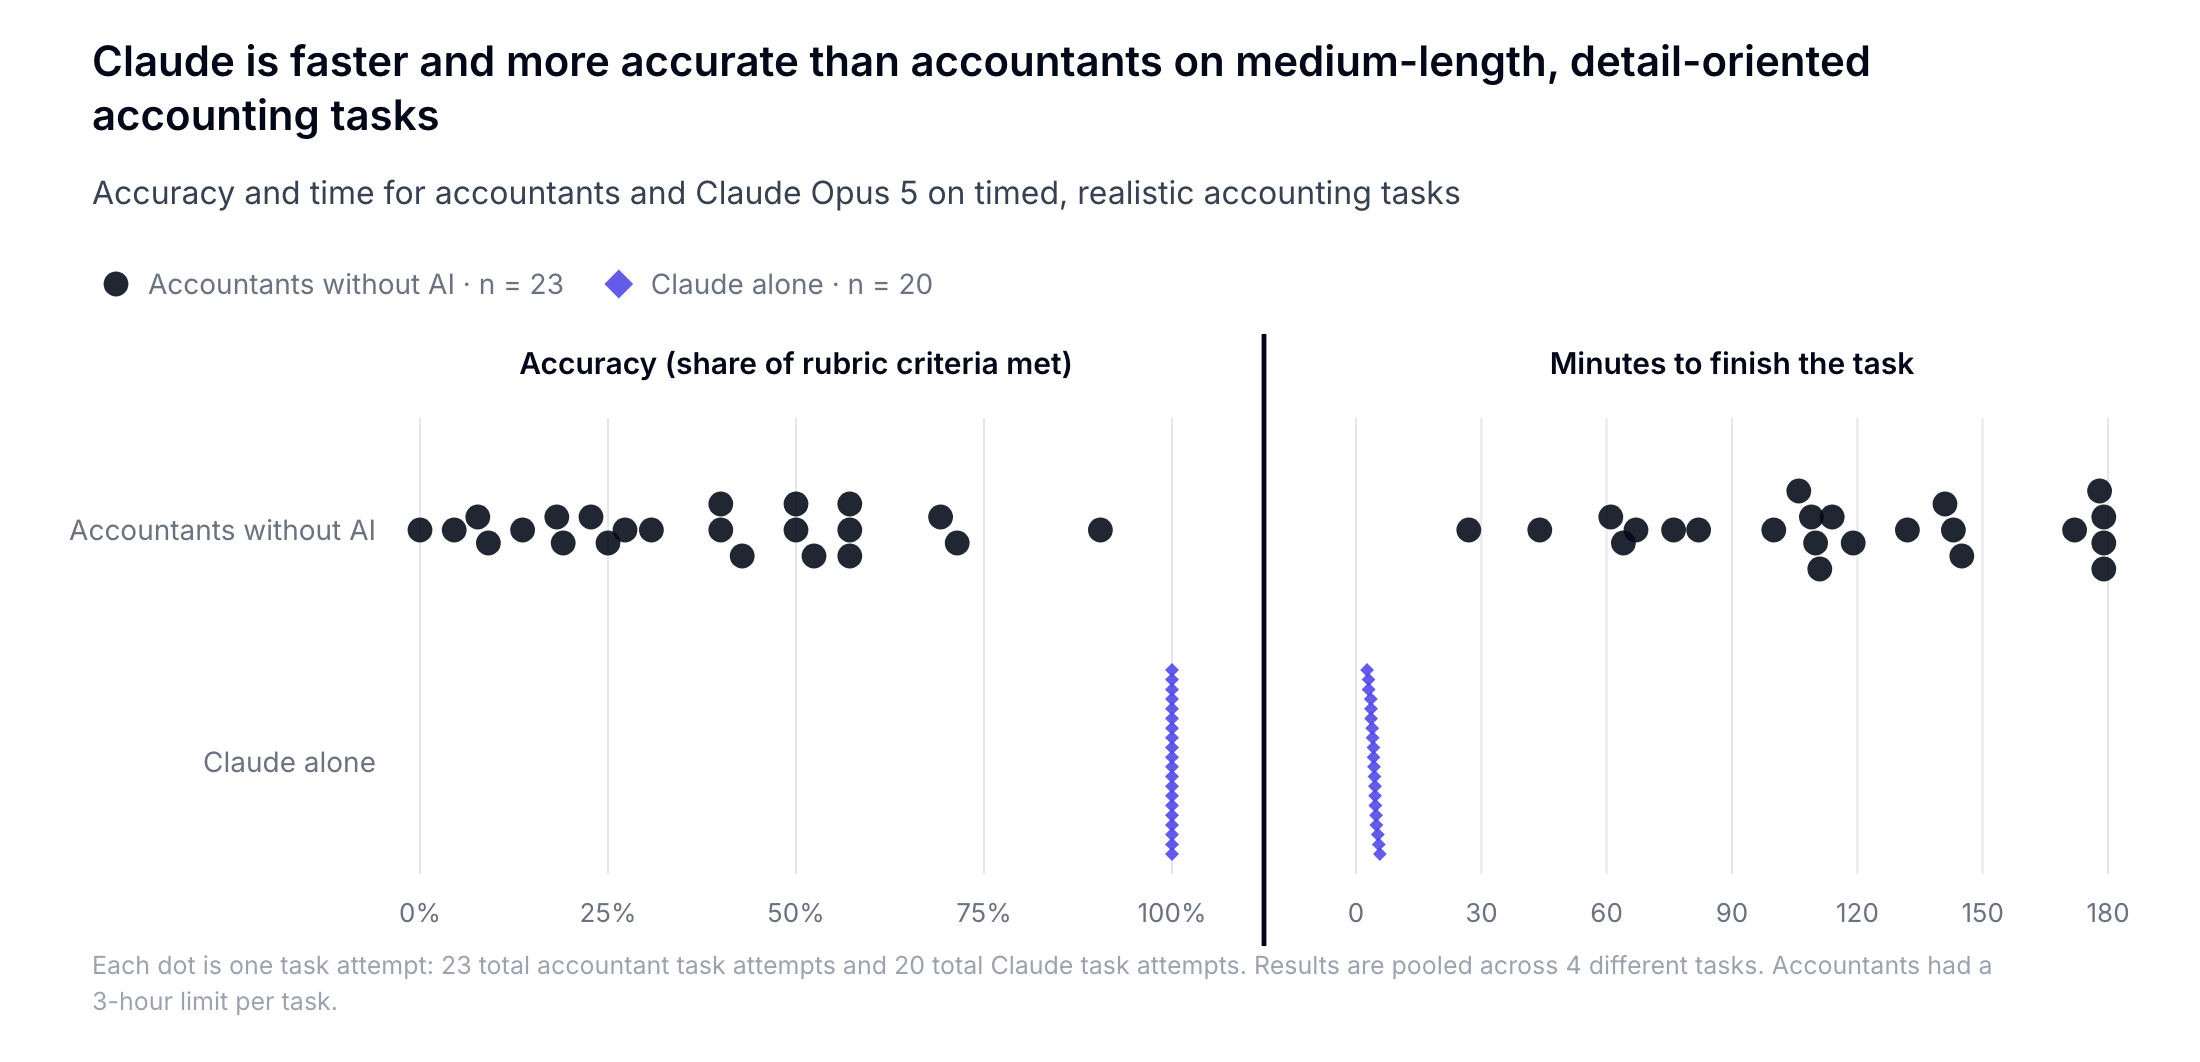
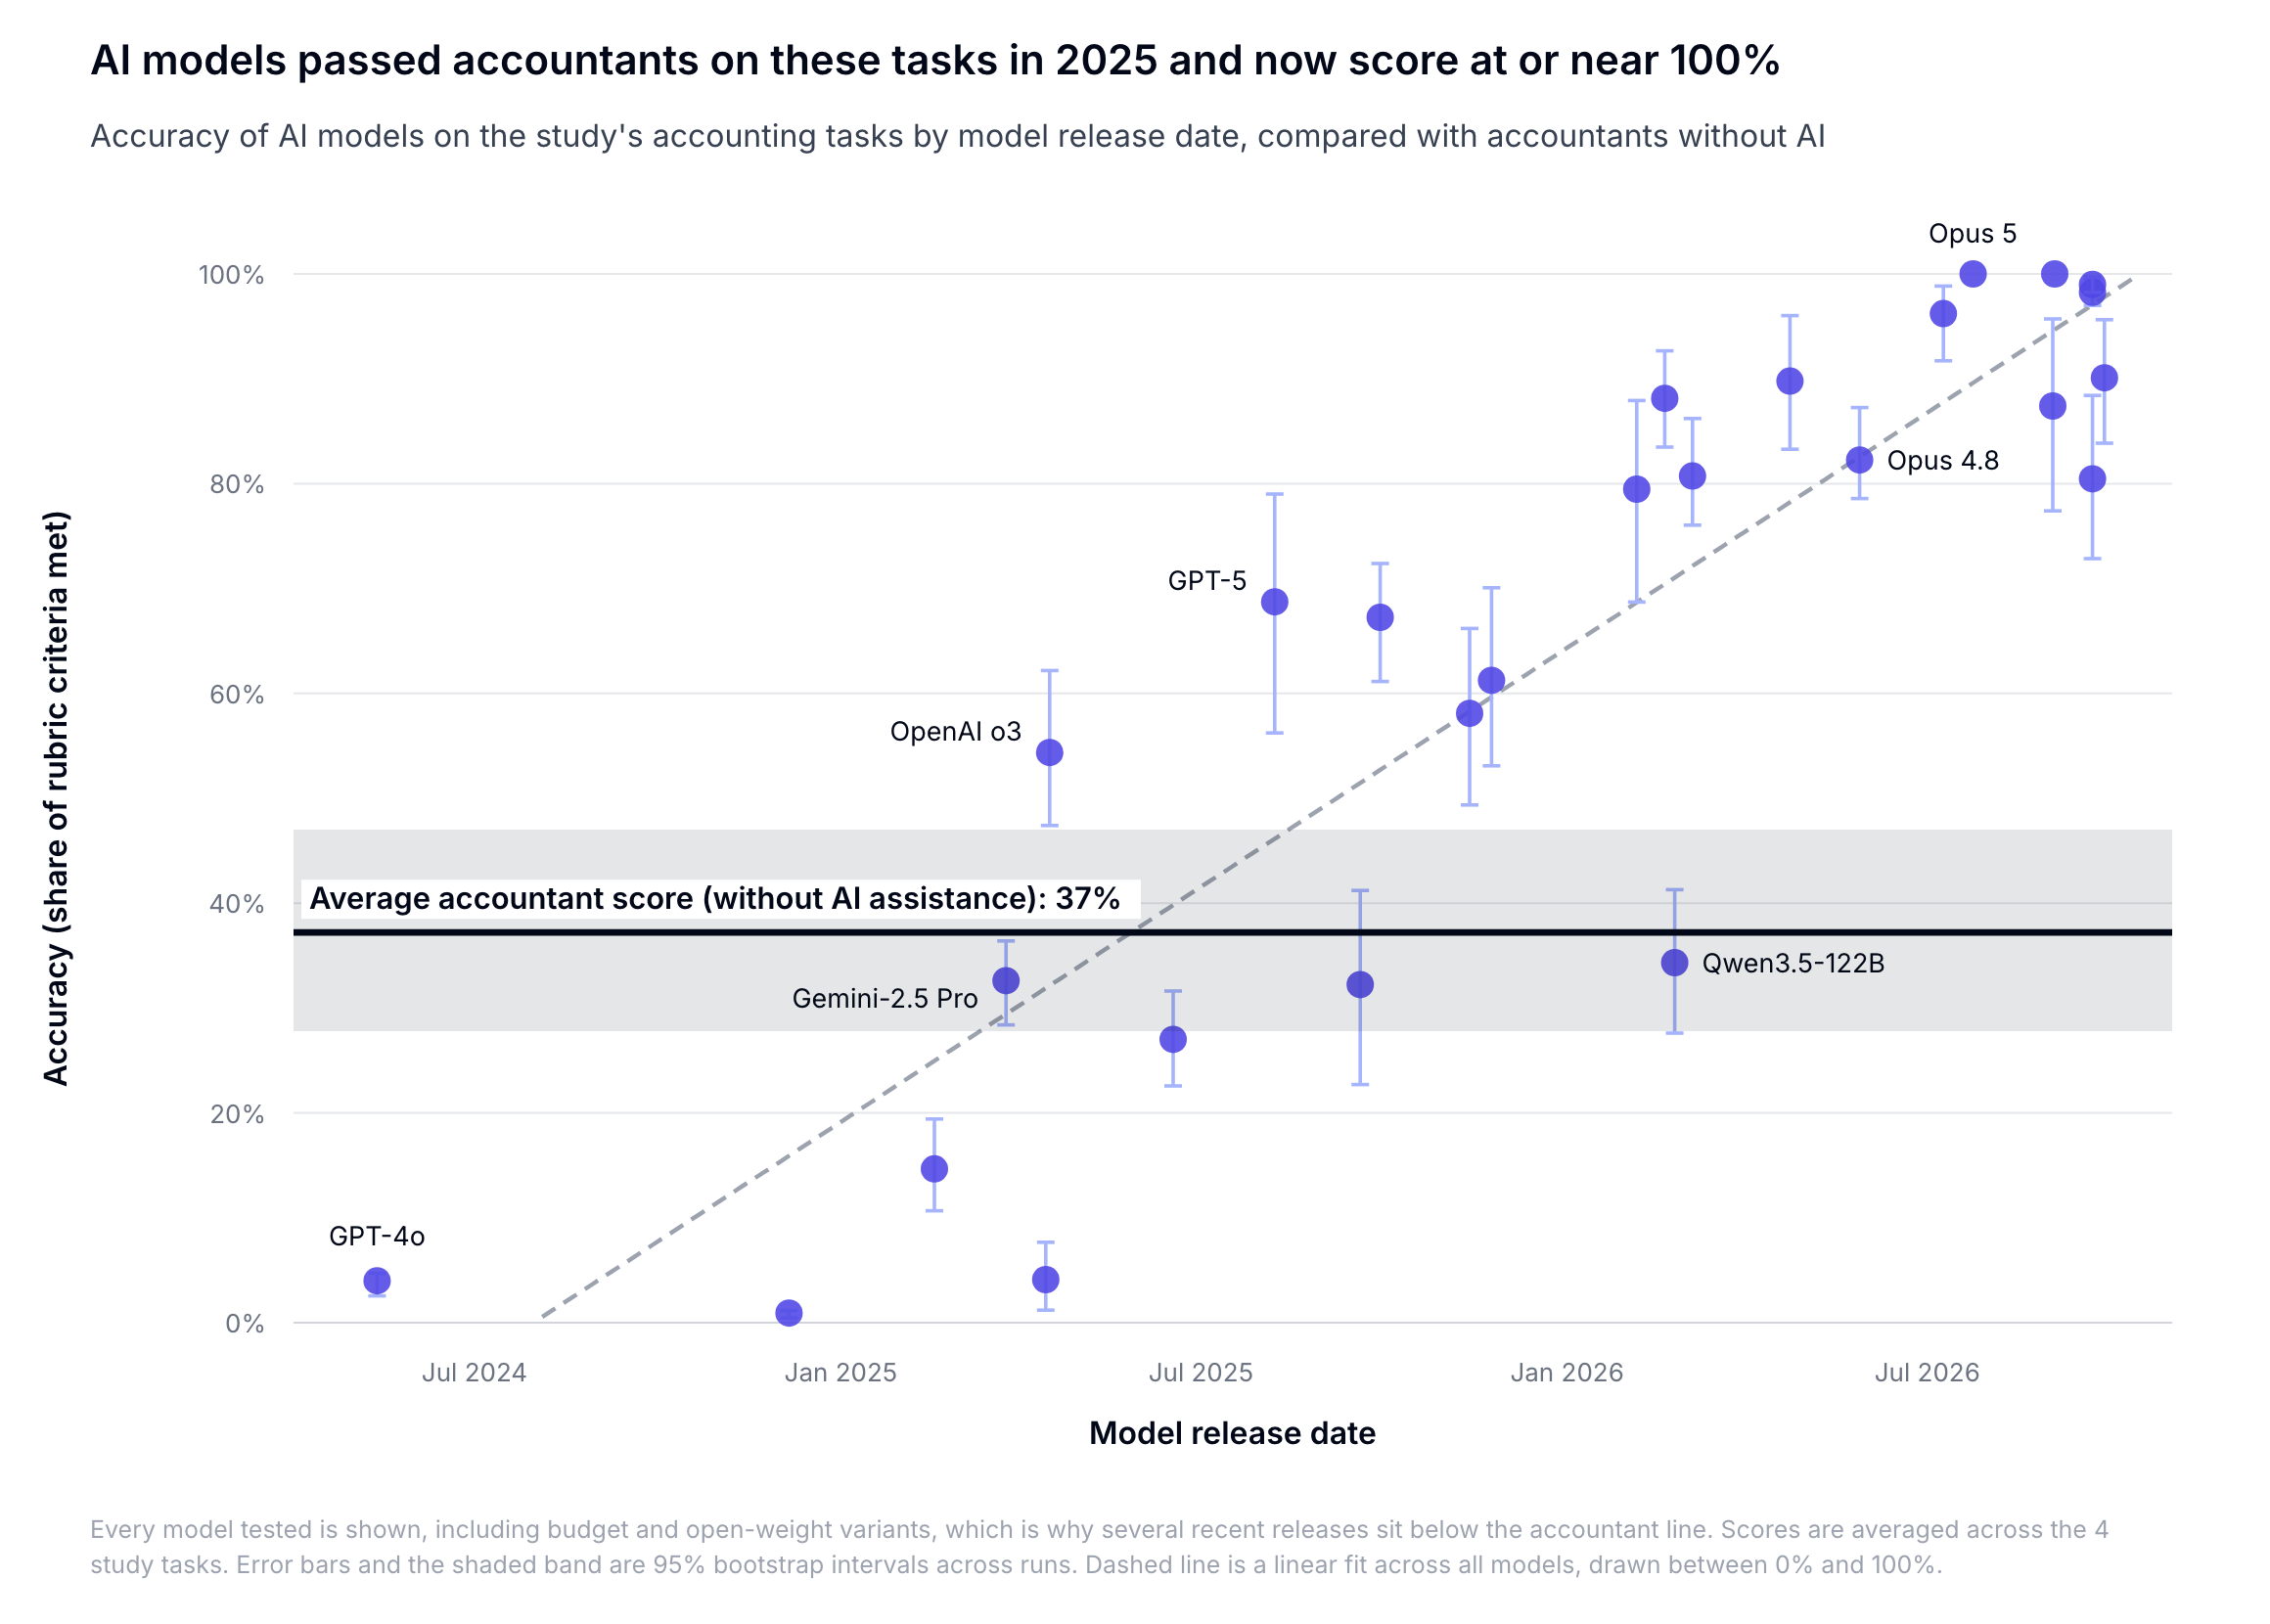
An AI system has achieved a perfect 100% score on an accounting task benchmark, where human professionals scored 37%, marking a reversal roughly 18 months in the making as the technology reached what the original assessment described as the "perfect" stage.
The comparison shows AI outperforming humans on accounting work by a wide margin — a full 63 percentage-point gap. The milestone is notable because, according to the claim, the positions were reversed 18 months earlier, when the benchmark stood at a stage where AI had not yet reached the "perfect" level.
Accounting tasks have been viewed as a demanding test for large language models (LLMs), requiring precision and adherence to rules rather than open-ended generation. A 100% result against a 37% human score, if it holds, would represent one of the clearest cases of AI surpassing professionals on a structured knowledge task. The precise identity of the benchmark, the group of human test-takers, and the testing conditions were not detailed in the available material.
The available information does not specify which AI model produced the 100% score, nor how the human participants were selected or measured. Details such as the task format, scoring methodology, and whether the human baseline reflects experienced accountants or a broader sample remain unconfirmed. Readers should treat the comparison as accurate in its headline figures but limited in verifiable context.
The core numbers — AI at 100% and humans at 37% on the accounting task, roughly 18 months after the technology had not yet reached that level — match the claim as presented, though supporting details are sparse. On that basis, the assessment is Mostly True.