AI · SEMICONDUCTOR · FACT CHECK
 SKD WIRE
Mostly True
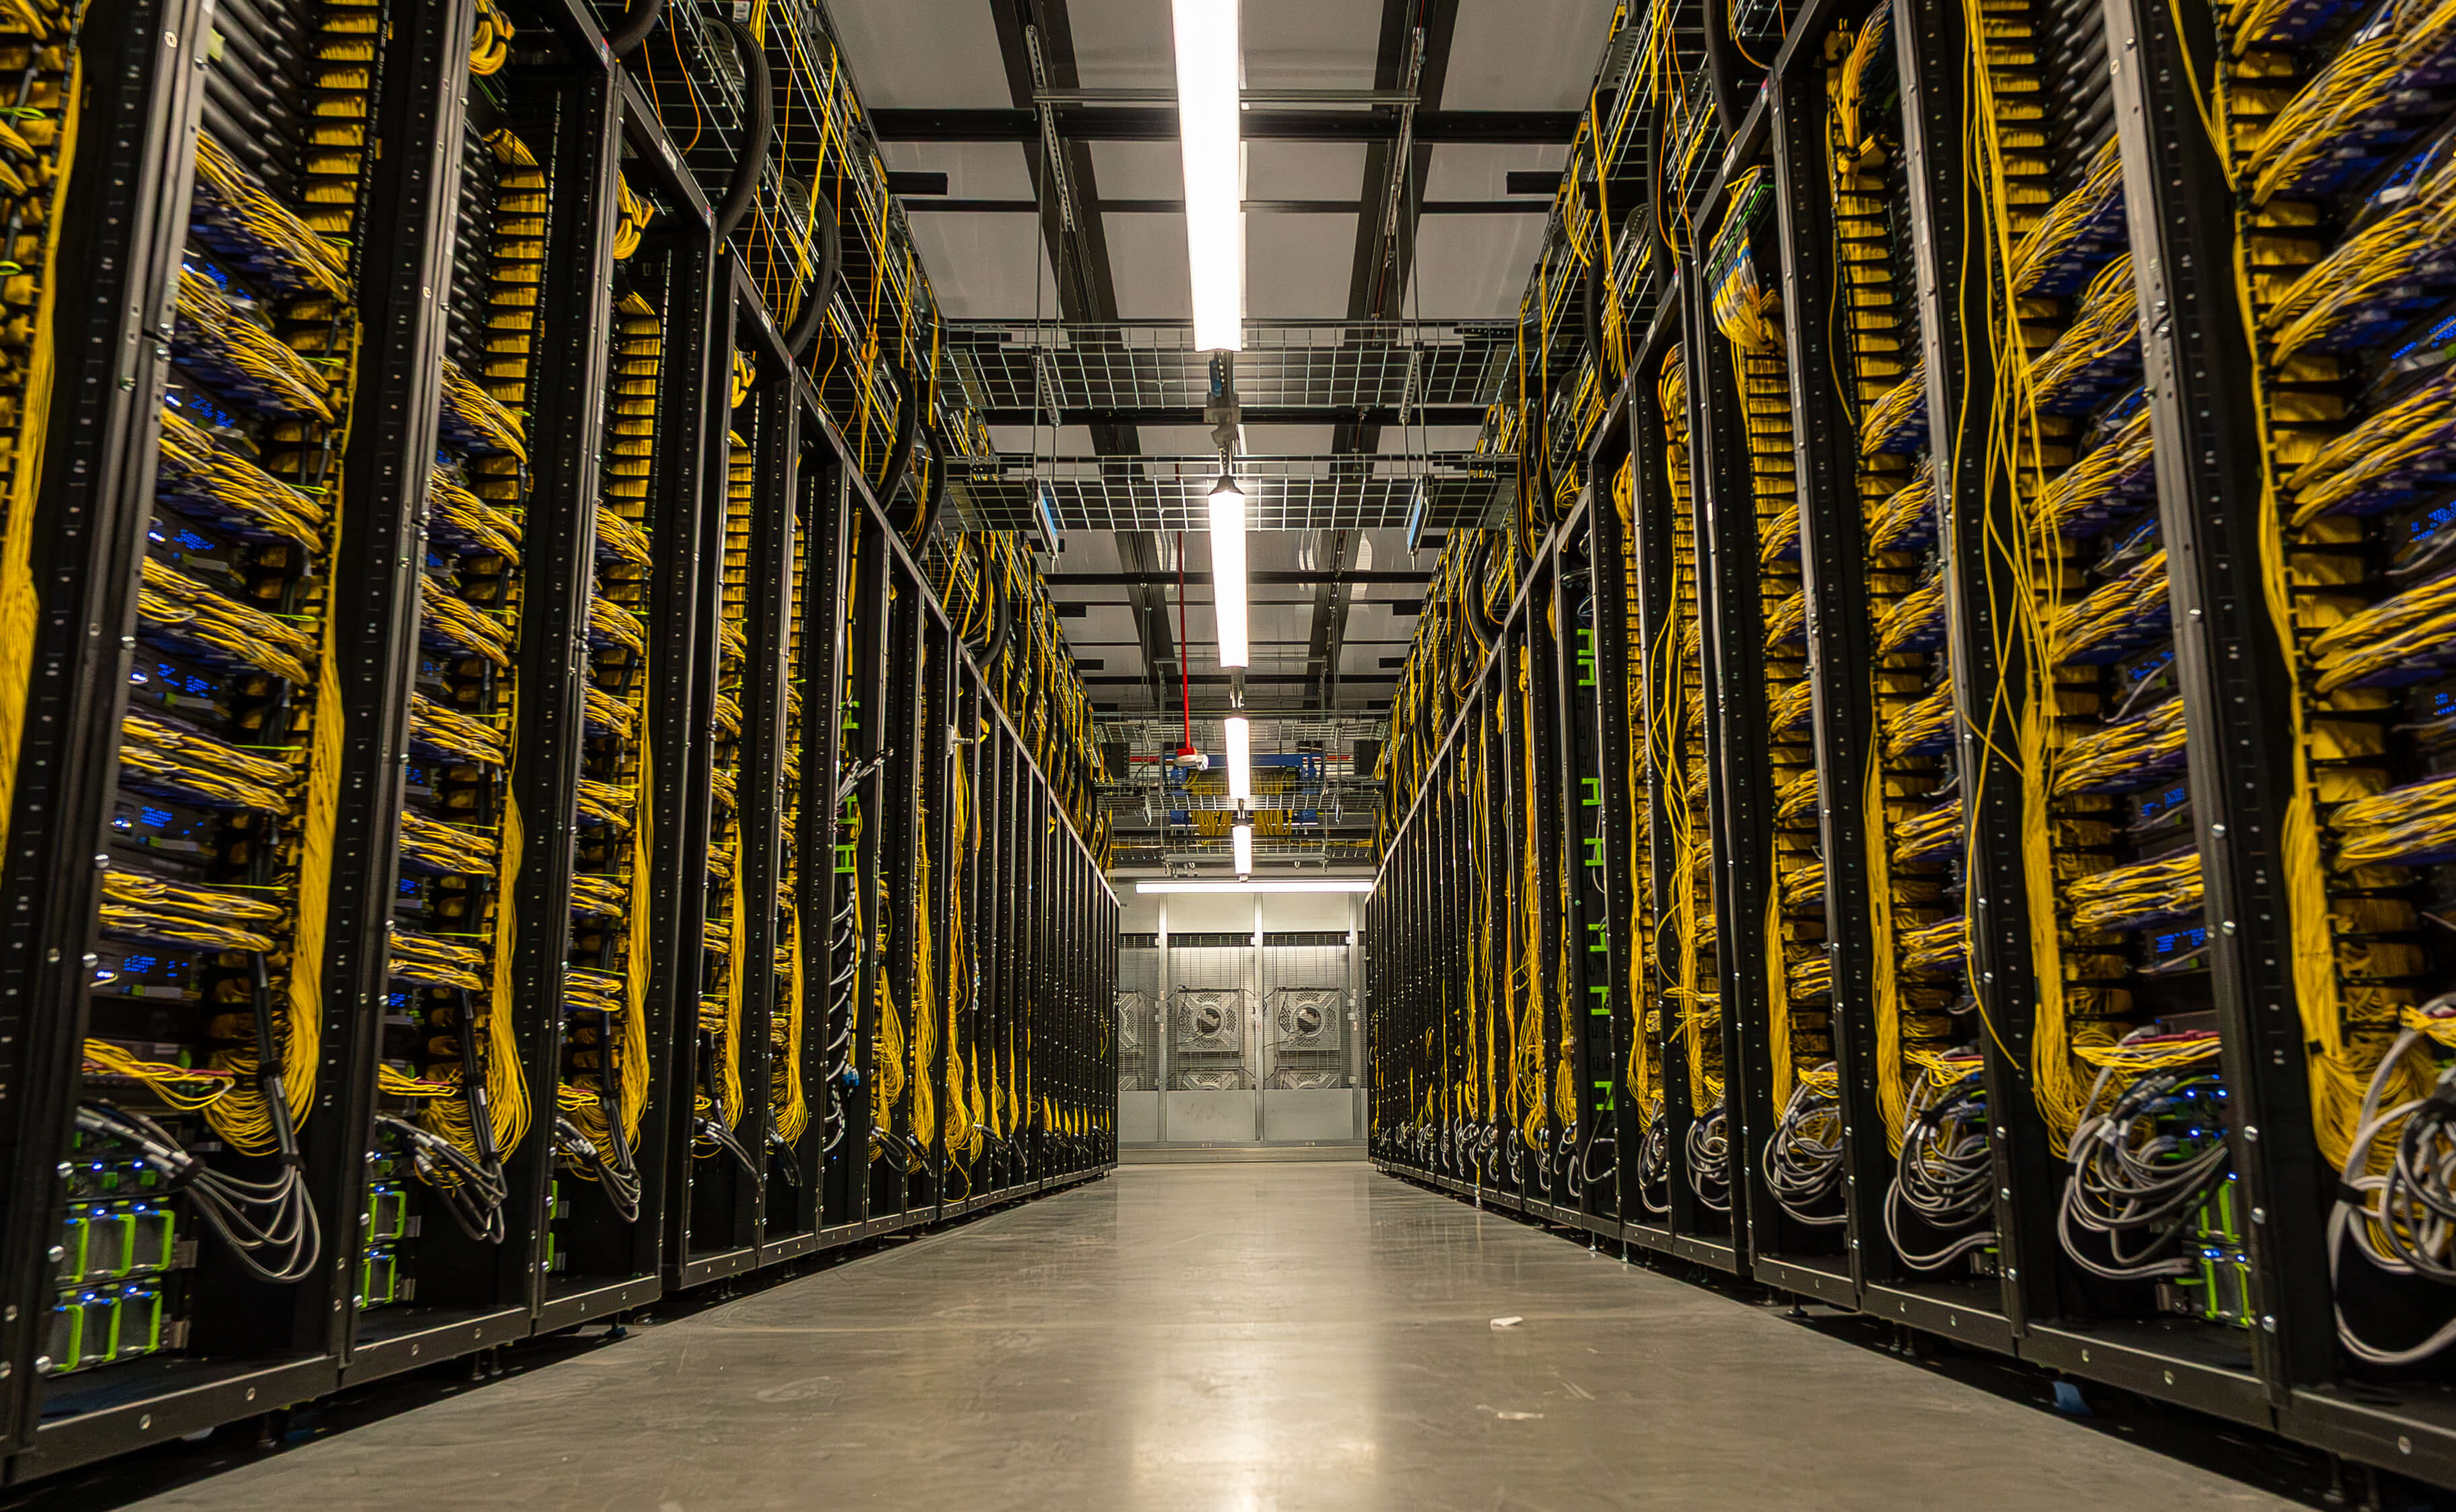
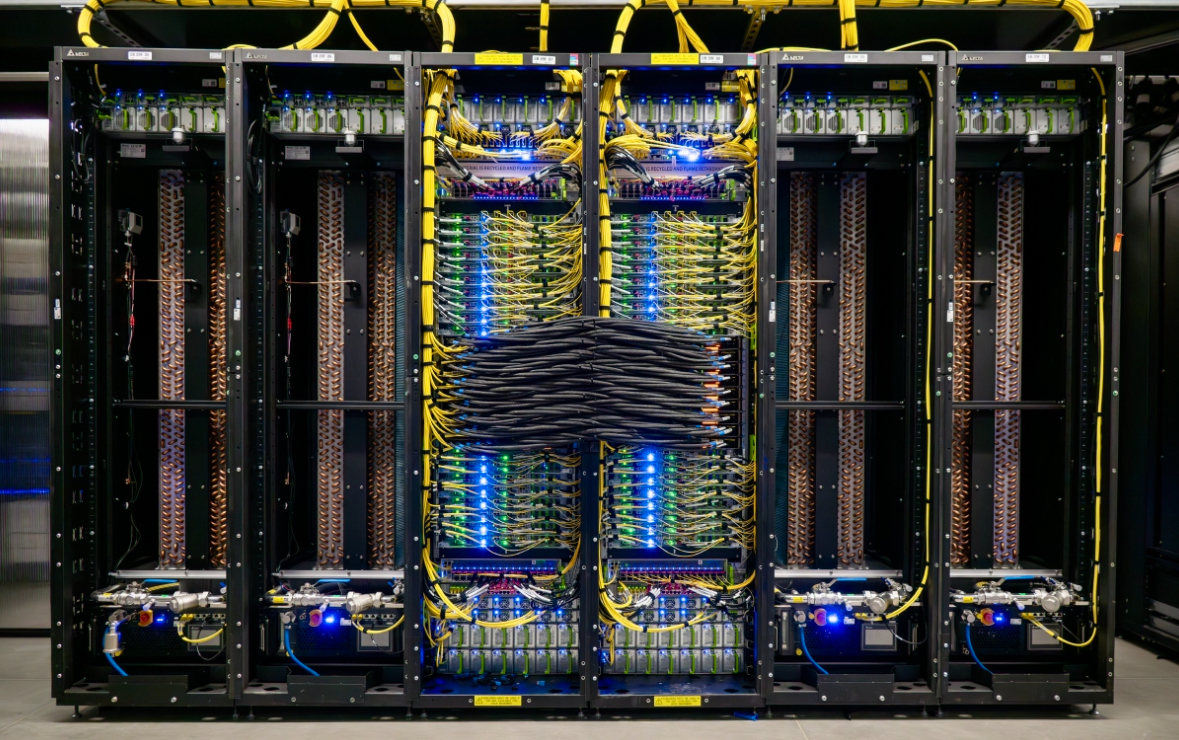
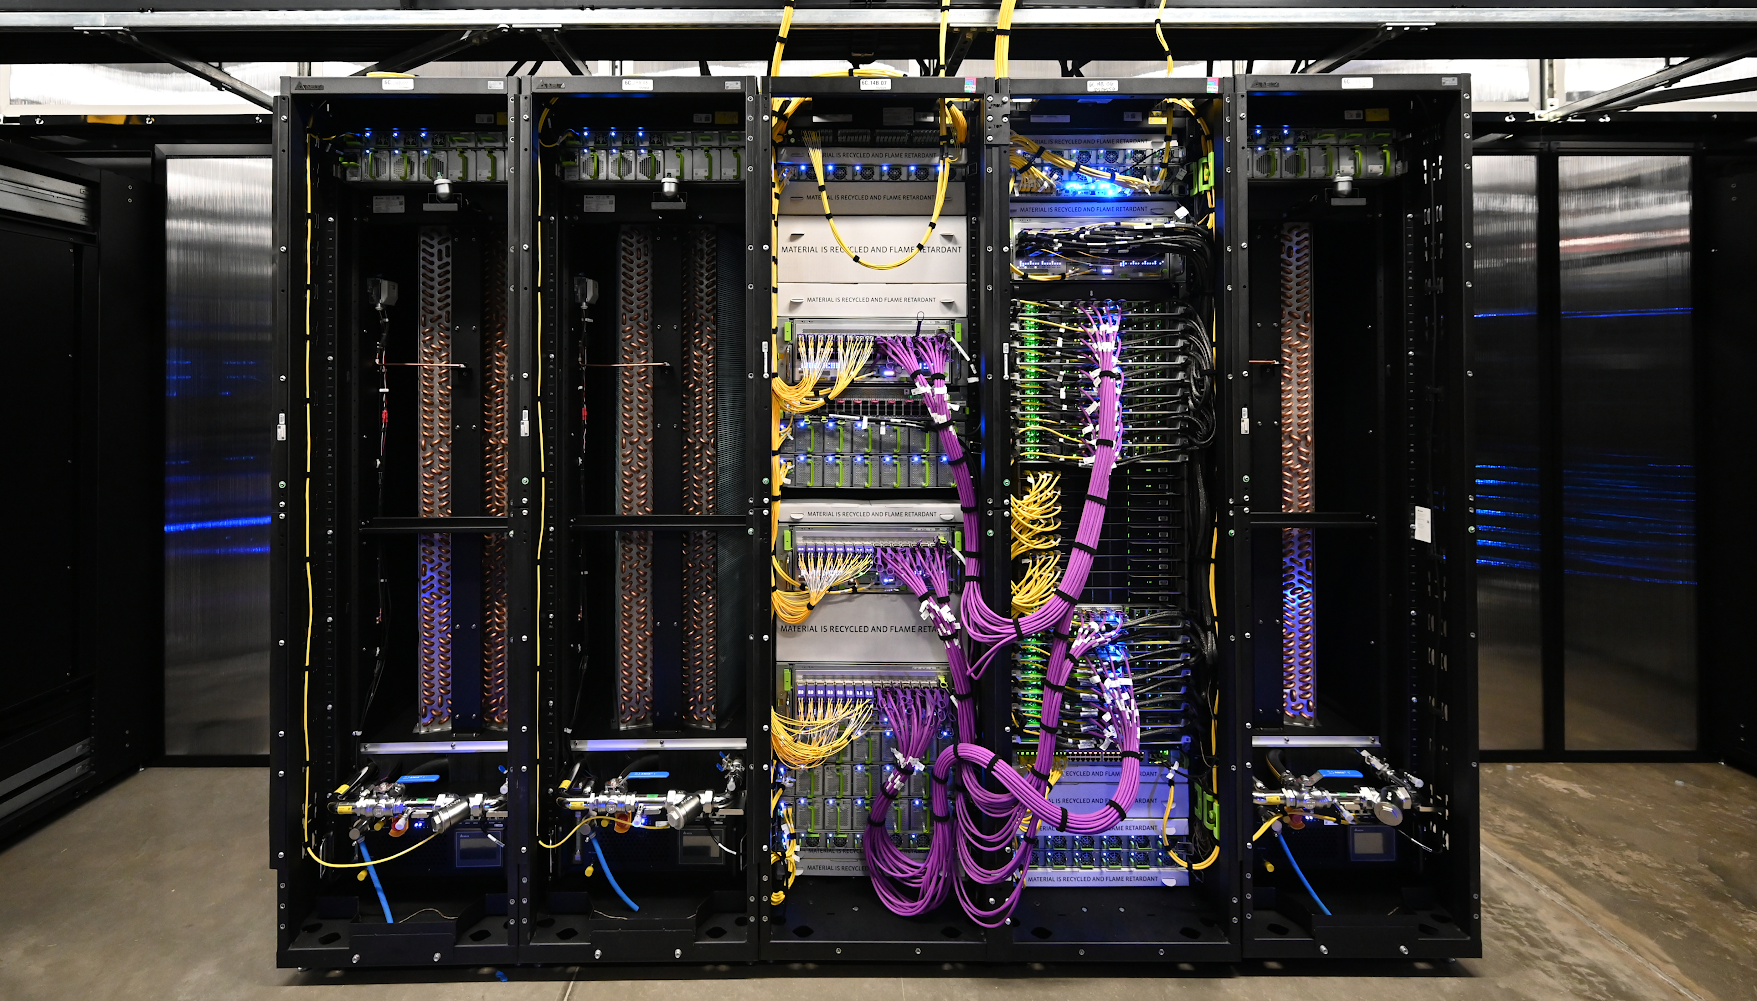
Meta has publicly detailed Prometheus, a system it says addresses training bottlenecks arising from the use of hundreds of thousands of GPUs, with the company positioning the work as a foundation for its Muse AI efforts. The disclosure, published on Meta's engineering blog, outlines how the company is tackling inefficiencies in large-scale model training infrastructure.
Meta said that training runs involving hundreds of thousands of GPUs create bottlenecks that limit how effectively the hardware fleet can be utilized. Prometheus is the company's response, presented as infrastructure designed to keep such massive training clusters running at high efficiency.
The system's release is tied to Muse AI, Meta's AI model effort, which the company says benefits directly from the improvements Prometheus brings to large-scale training.
The information comes from Meta's own engineering blog, and the company has not released independent benchmarks or third-party assessments of the claimed improvements. As with most large-scale infrastructure disclosures, the exact performance gains and the precise fleet size involved remain as described by Meta rather than externally measured.
The announcement is notable for its scale, however. Few companies operate GPU fleets of the size Meta describes, making the engineering lessons published in the blog post of interest to other firms pursuing frontier-scale AI training.
Meta's blog post, along with supporting materials released alongside it, forms the basis of the company's account of the Prometheus system and its role in supporting Muse AI. The overall picture presented — that Meta has taken a significant step against training bottlenecks at extreme GPU scale — is broadly supported by the company's disclosure, though its full impact awaits outside confirmation. On balance, the claim lands as Mostly True.