AI · SEMICONDUCTOR · FACT CHECK
 SKD WIRE
True
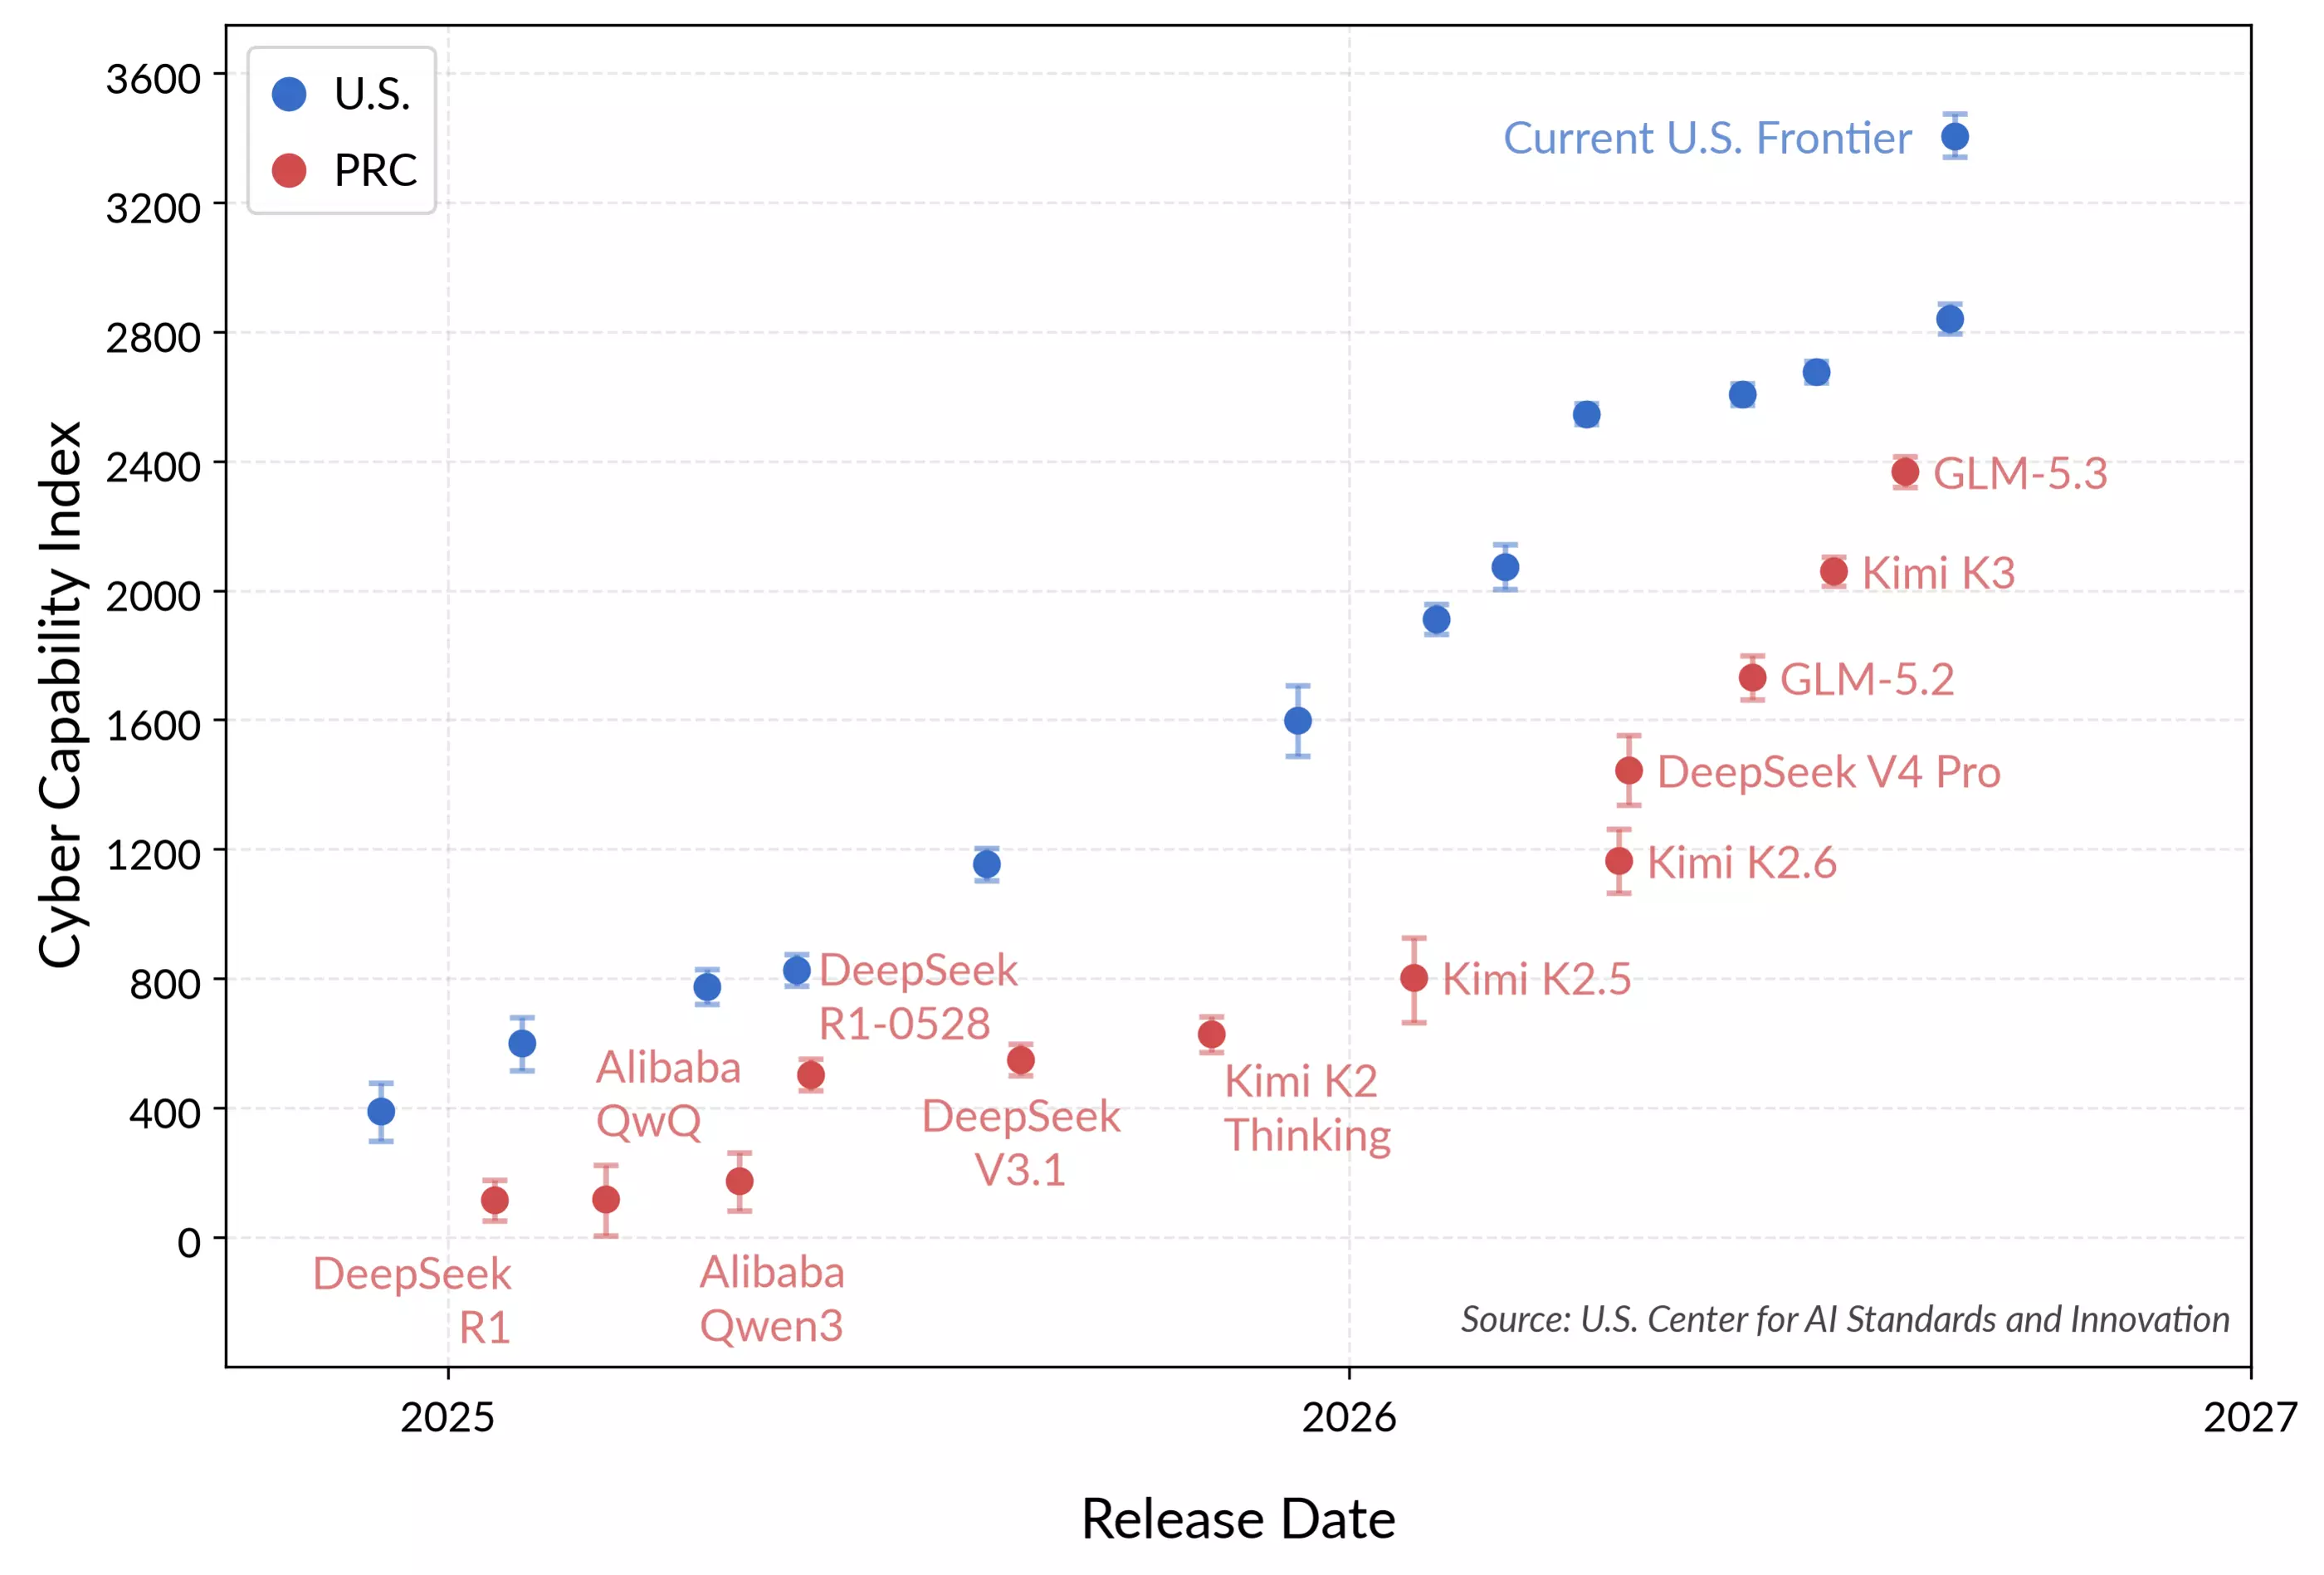
Anthropic has assessed that GLM-5.3, a large language model developed in China, demonstrates hacking capability on par with its own Claude models, while finding that the model's built-in safety guardrails can be bypassed with relative ease, according to the company's evaluation.
In its assessment, Anthropic described GLM-5.3 as reaching a hacking capability level comparable to Claude, placing the Chinese model in the same tier as its own frontier systems when it comes to offensive cyber tasks. The finding signals that capabilities once thought to be the preserve of a handful of leading US laboratories are now appearing in models developed by Chinese AI companies.
The more cautionary element of the evaluation concerned safety. Anthropic found that GLM-5.3's safeguards — the mechanisms intended to prevent the model from assisting with harmful cyber activity — could be circumlected without significant effort, according to the company's testing. In other words, the model's offensive skill is not matched by equivalent defensive robustness.
The gap between capability and controllability is the core of Anthropic's concern. A model with Claude-class hacking ability but fragile guardrails presents a different risk profile from a model whose capabilities are constrained by reliable safety measures. Anthropic's evaluation frames this combination — high offensive capability paired with easily bypassed protections — as the noteworthy outcome.
The assessment reflects Anthropic's ongoing practice of benchmarking competing frontier models against its own systems, particularly on tasks with security implications. The company has positioned evaluations of this kind as part of its effort to inform understanding of where rival models stand on both performance and safety.
GLM-5.3's reported performance indicates that Chinese-developed LLMs are closing the gap with US frontier models not only on general benchmarks but also on specialized cybersecurity tasks. Anthropic's finding that the model's safety guardrails are easily bypassed, alongside its Claude-level hacking capability, is true.