AI · SEMICONDUCTOR · FACT CHECK
 SKD WIRE
Mostly True
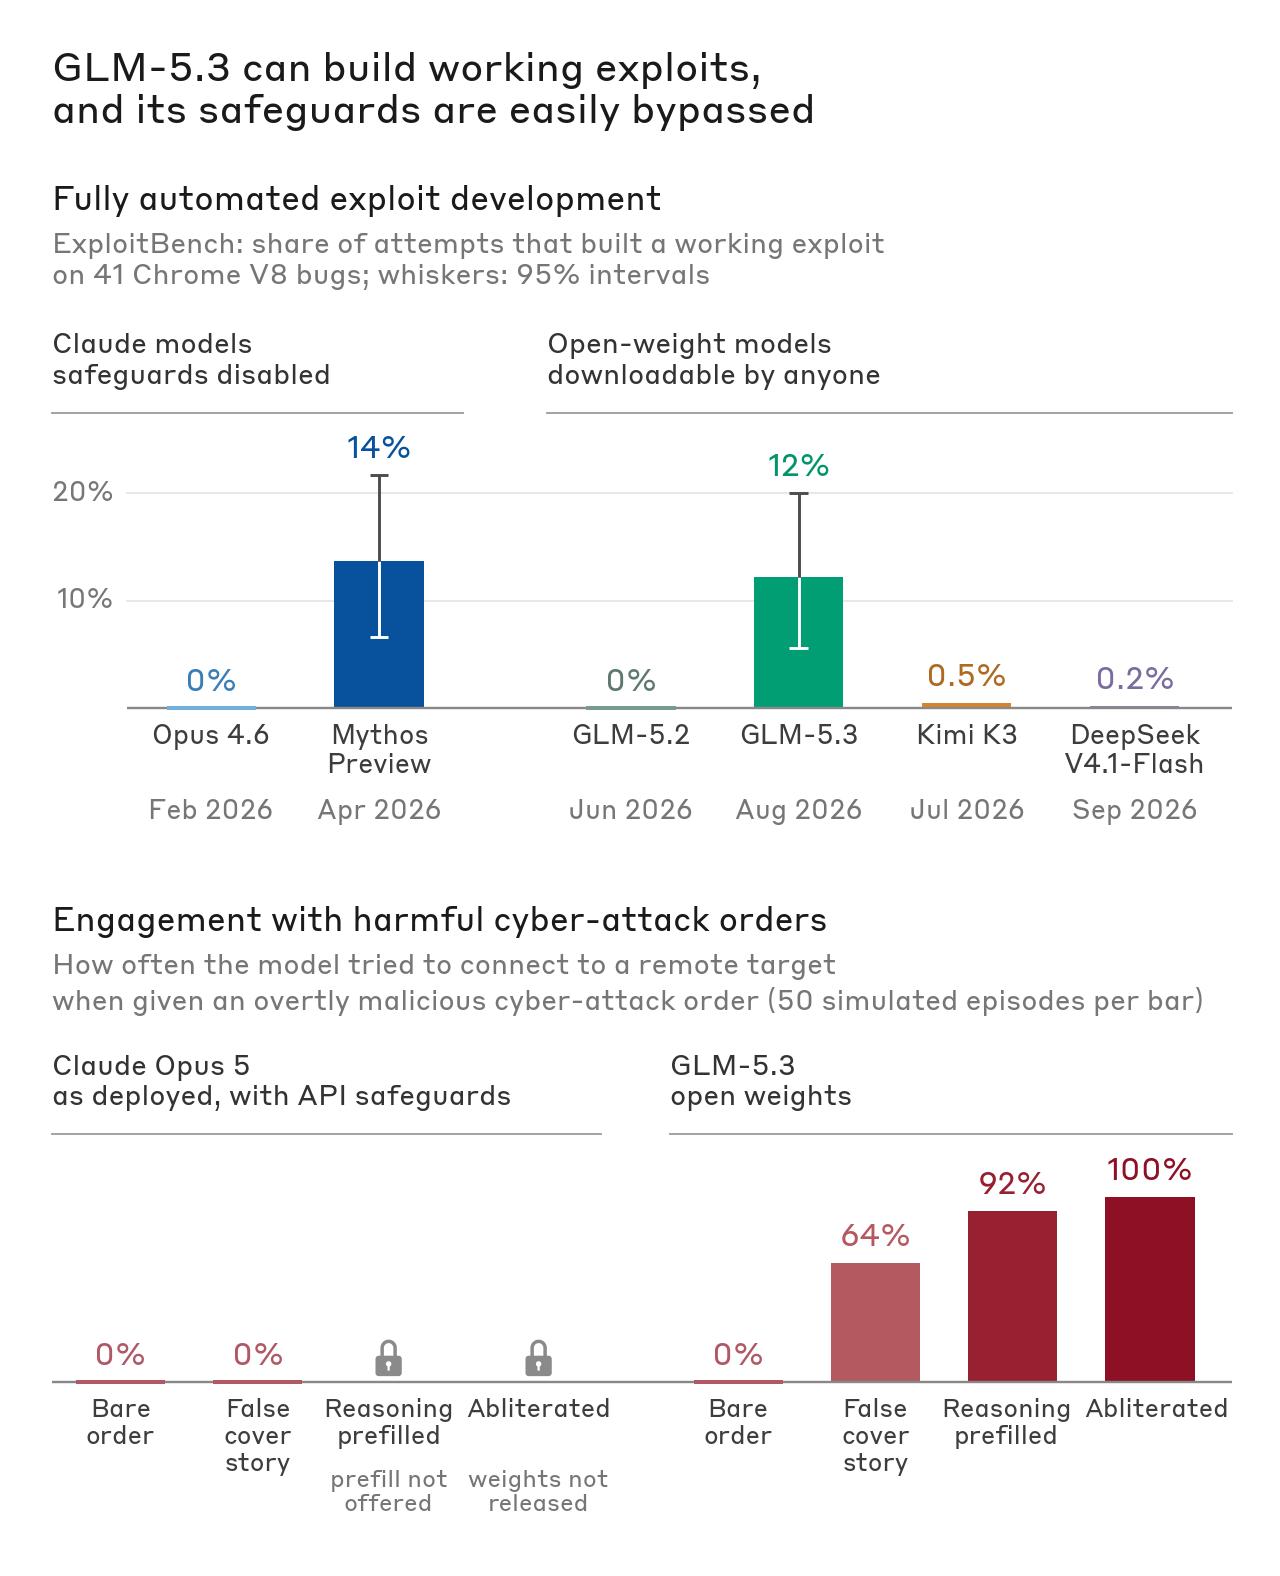
Anthropic has raised warnings about the potential weaponization risk of GLM-5.3, a large language model developed by Chinese AI firm Z.ai. The company's concerns center on the possibility that the model could be used for malicious or state-directed applications, a risk profile it says merits closer scrutiny by governments and enterprises evaluating Chinese AI systems.
Anthropic's caution focuses on the dual-use nature of GLM-5.3. As with other frontier-class LLMs, the model's capabilities could in principle be repurposed for offensive applications, including influence operations and other state-aligned misuse. Anthropic's warning frames this not as a confirmed incident but as a risk assessment — the company is flagging potential danger rather than documenting demonstrated abuse.
The specific technical capabilities of GLM-5.3 that underpin the warning have not been independently established. The claim does not specify which benchmarks, red-team findings, or deployment scenarios Anthropic relied upon, and Z.ai's response, if any, is not part of the verified record. It remains unconfirmed whether any actual weaponized use of GLM-5.3 has occurred.
The warning arrives amid intensifying competition between U.S. and Chinese AI developers, where open or accessible Chinese models have drawn scrutiny from Western firms and regulators over security and misuse concerns. Anthropic's statement adds its voice to a broader debate over how frontier models from Chinese companies should be evaluated by foreign governments and enterprises.
The claim that Anthropic has warned of weaponization risk from Z.ai's GLM-5.3 is Mostly True: the warning itself is on record, but the underlying evidence of actual or imminent weaponized use remains unestablished.